HabrProject PageTechnical Report (soon)Models🤗ComfyUI README
Kandinsky 5.0: A family of diffusion models for Video & Image generation
In this repository, we provide a family of diffusion models to generate a video or an image given a textual prompt and distilled model for faster generation.
Project Updates
- 🔥 2025/09/29: We have open-sourced Kandinsky 5.0 T2V Lite a lite (2B parameters) version of Kandinsky 5.0 Video text-to-video generation model. Released checkpoints:
kandinsky5lite_t2v_pretrain_5s,kandinsky5lite_t2v_pretrain_10s,kandinsky5lite_t2v_sft_5s,kandinsky5lite_t2v_sft_10s,kandinsky5lite_t2v_nocfg_5s,kandinsky5lite_t2v_nocfg_10s,kandinsky5lite_t2v_distilled16steps_5s,kandinsky5lite_t2v_distilled16steps_10scontains weight from pretrain, supervised finetuning, cfg distillation and diffusion distillation into 16 steps. 5s checkpoints are capable of generating videos up to 5 seconds long. 10s checkpoints is faster models checkpoints trained with NABLA algorithm and capable to generate videos up to 10 seconds long. - 🔥 2025/10/7: The ComfyUI README file has been updated. SDPA support has been added, allowing you to run our code without Flash attention. Magcache support for nocfg checkpoints has been added, allowing Magcache support for sft and nocfg checkpoints. Memory consumption in the VAE has been reduced, with the entire pipeline now running at 24 GB with offloading.
Kandinsky 5.0 T2V Lite
Kandinsky 5.0 T2V Lite is a lightweight video generation model (2B parameters) that ranks #1 among open-source models in its class. It outperforms larger Wan models (5B and 14B) and offers the best understanding of Russian concepts in the open-source ecosystem.
We provide 8 model variants, each optimized for different use cases:
- SFT model — delivers the highest generation quality;
- CFG-distilled — runs 2× faster;
- Diffusion-distilled — enables low-latency generation with minimal quality loss (6× faster);
- Pretrain model — designed for fine-tuning by researchers and enthusiasts.
All models are available in two versions: for generating 5-second and 10-second videos.
Pipeline
Latent diffusion pipeline with Flow Matching.
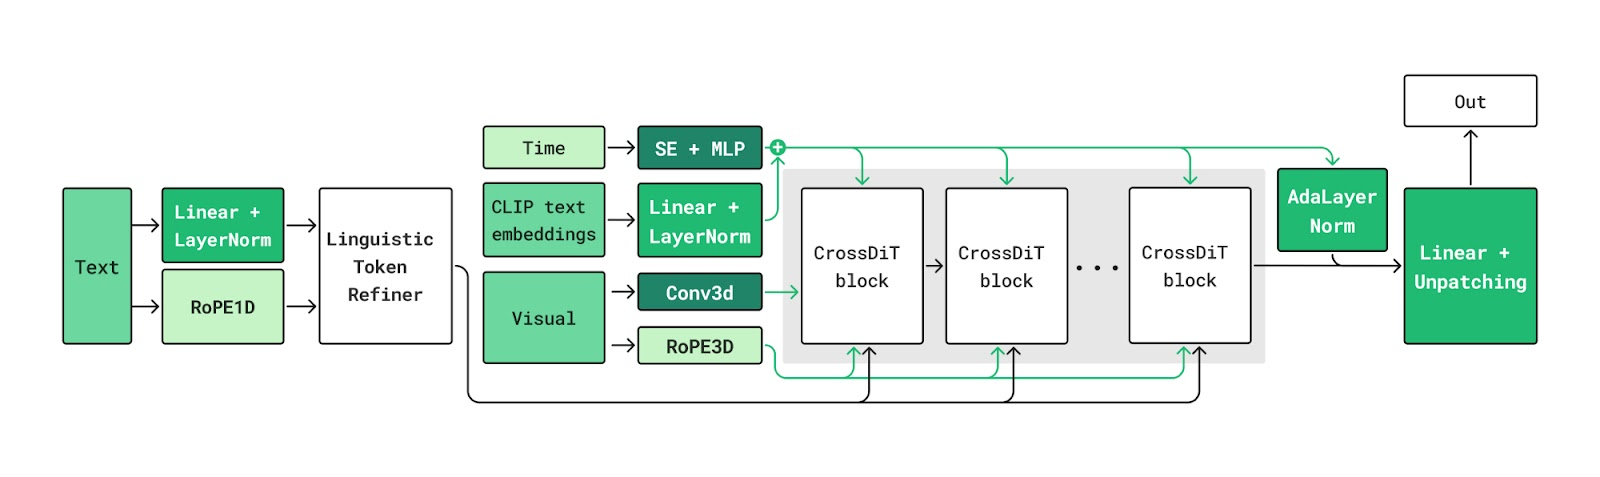
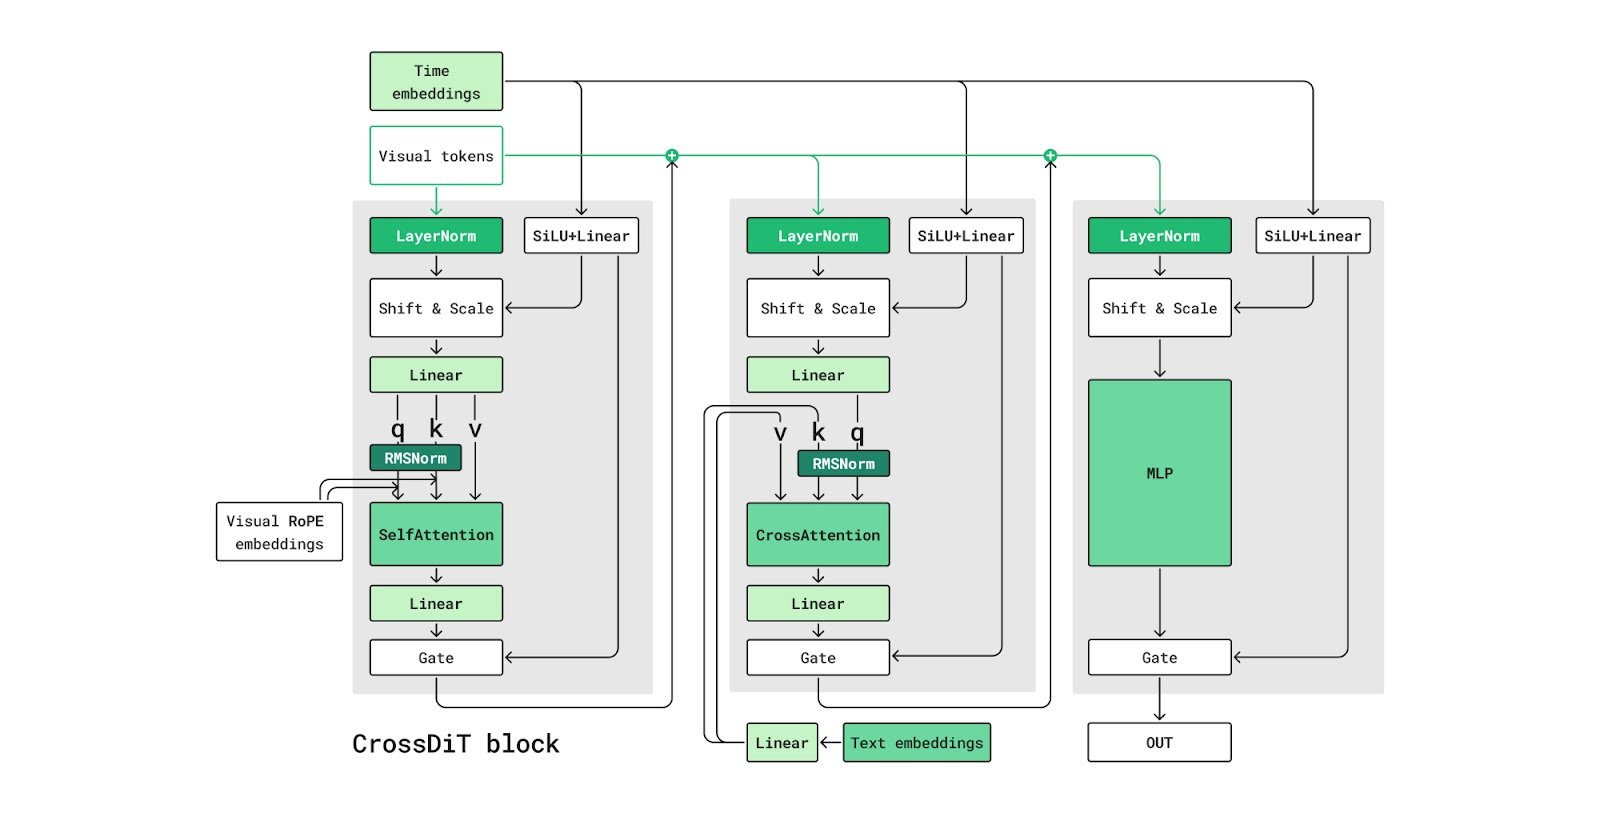
Diffusion Transformer (DiT) as the main generative backbone with cross-attention to text embeddings.
- Qwen2.5-VL and CLIP provides text embeddings.
- HunyuanVideo 3D VAE encodes/decodes video into a latent space.
- DiT is the main generative module using cross-attention to condition on text.